AMD Capsaicin Framework
Capsaicin is a Direct3D12 framework for real-time graphics research which implements the GI-1.0 technique and a reference path-tracer.

Large diffusion models can generate images with convincing illumination directly from strong learned priors. At the The 19th European Conference on Computer Vision — ECCV 2026 we are presenting a generative method for global illumination (GI) that produces geometrically aligned, temporally stable indirect lighting using a single-step latent diffusion model. Unlike iterative or video diffusion methods that are costly and hard to control, our model conditions a one-step image generator on scene-intrinsic signals and sparse lighting hints, and adds a Temporal VAE (TVAE) decoder for long-range temporal coherence — suitable for real-time rendering use cases with frame-by-frame generation.
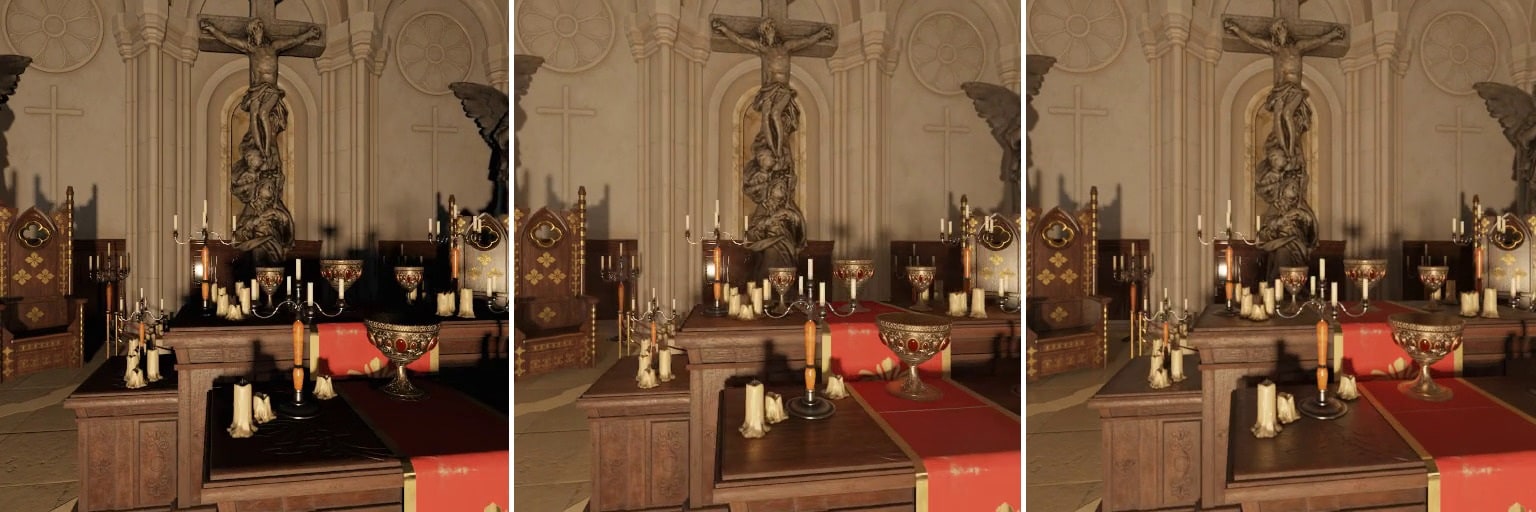 Figure 1. (Left) Direct lighting, (Middle) Our result, and (Right) Reference GI.
We begin by reframing the problem itself. We formulate the screen-space approximation of GI as a conditional image generation task (Figure 2). Building on a distilled single-step model, we fine-tune the diffusion UNet while keeping the VAE frozen. Direct lighting serves as the initial lighting hint, encoded through the VAE encoder, while geometry (normals), materials (albedo, roughness, metallic), and lighting cues (noisy GI, radiance cues) are injected at multiple UNet levels through T2I-Adapters. Routing conditions through adapters rather than concatenating them onto the noisy input preserves quality and enables efficient multi-scale conditioning. We also demodulate direct lighting by albedo before encoding, so the model focuses on illumination, then re-modulate on output to restore texture and color.
To keep long sequences stable, the TVAE decoder takes the current latent along with the previous output, reprojected using motion vectors. A small history encoder injects these signals via zero convolutions, so the decoder reuses pixels from the previous frame where the current latent is close to it — suppressing flicker while preserving detail. We train only the decoder and simply swap it in at inference time.
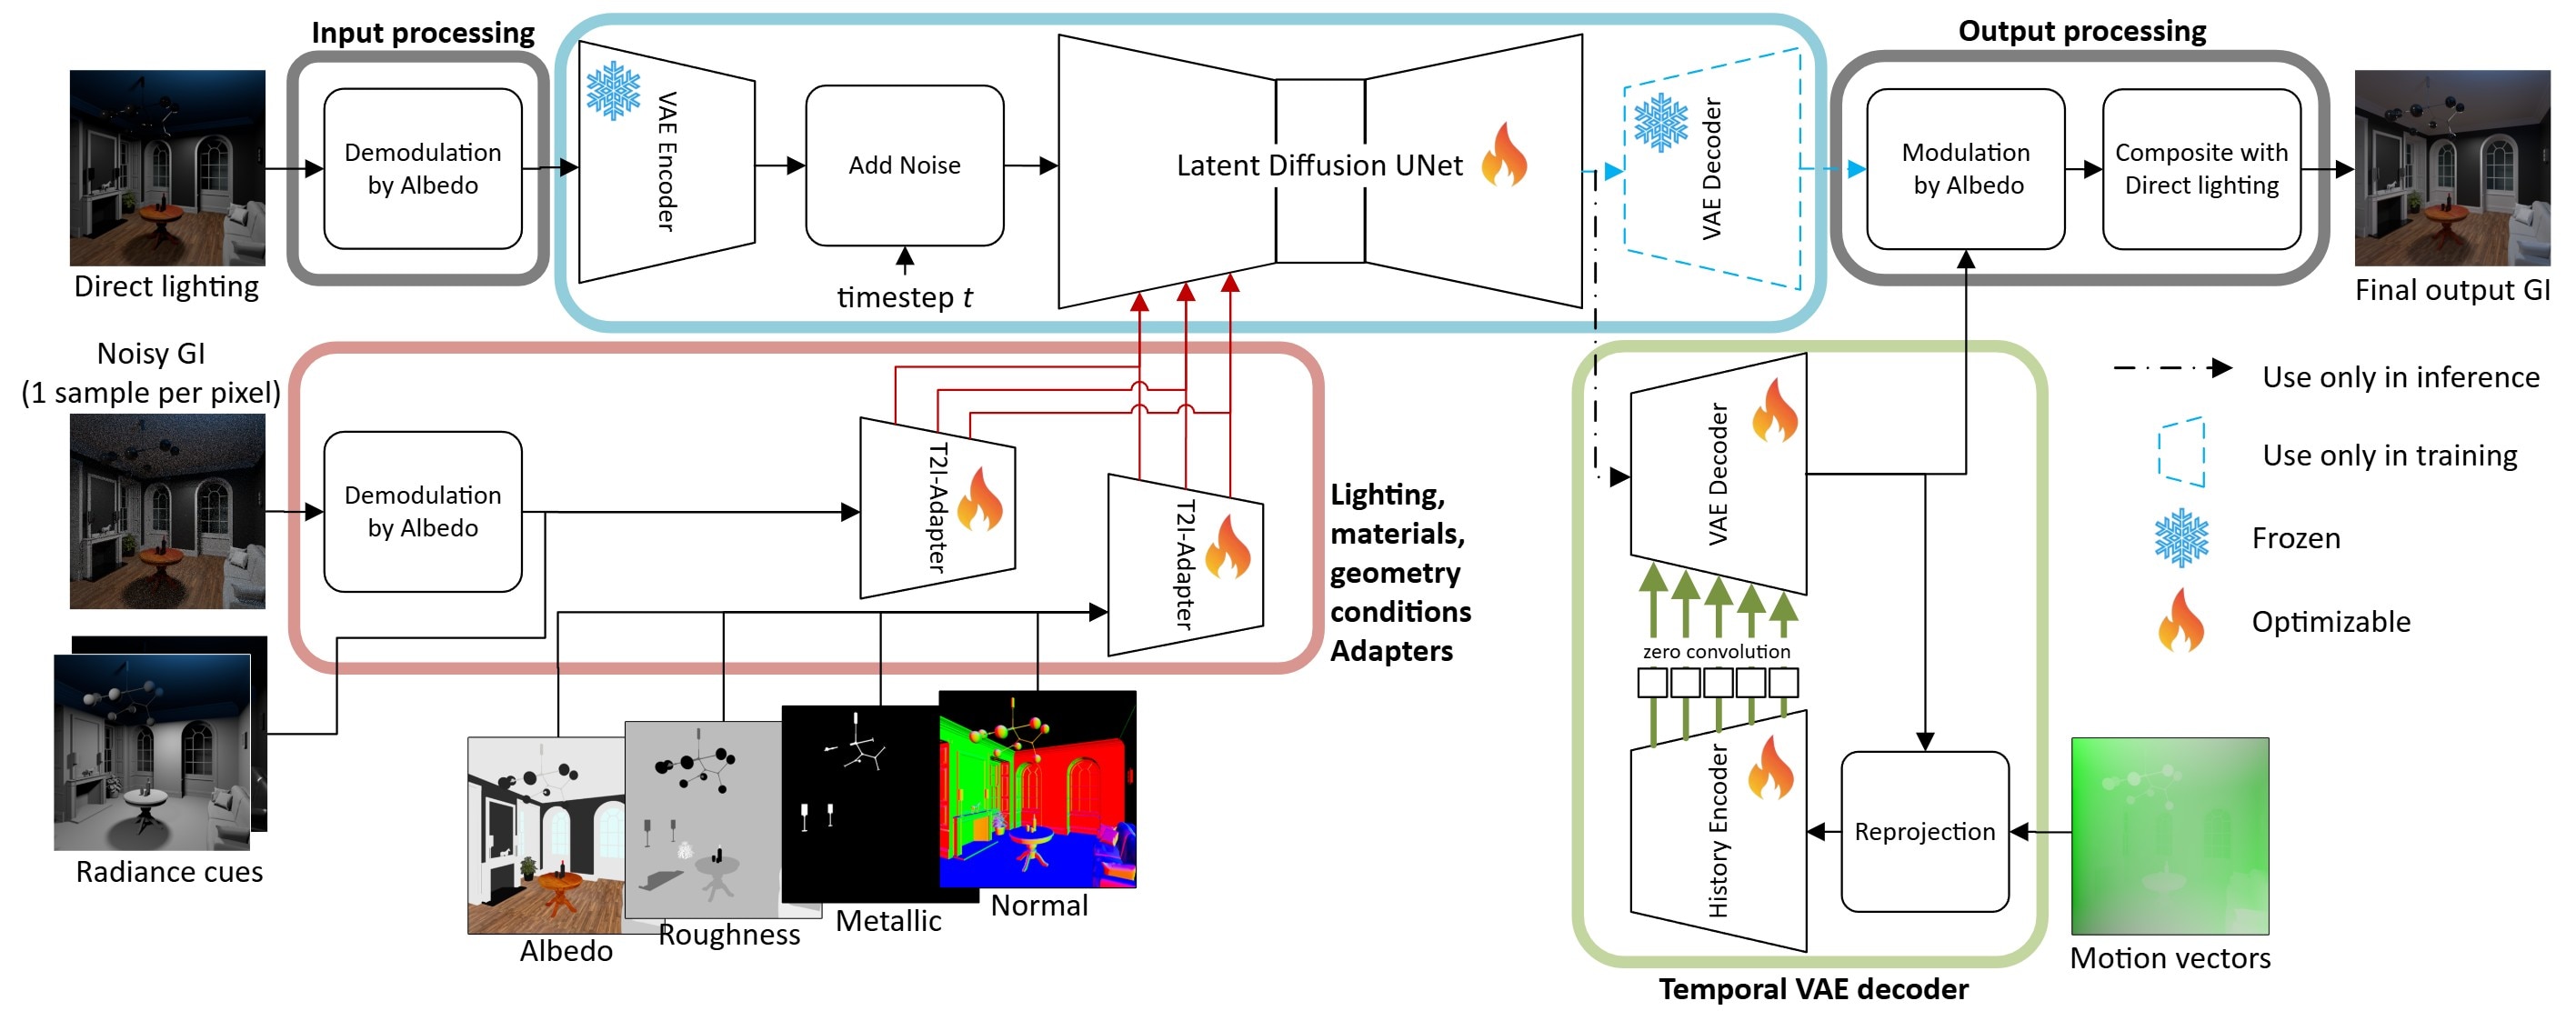 Figure 2. Overview of our method. Multiple conditioning inputs are encoded via adapter modules and injected into a one-step diffusion model. The Temporal VAE decoder ensures temporal consistency over long sequences and replaces the frozen VAE decoder at inference time.
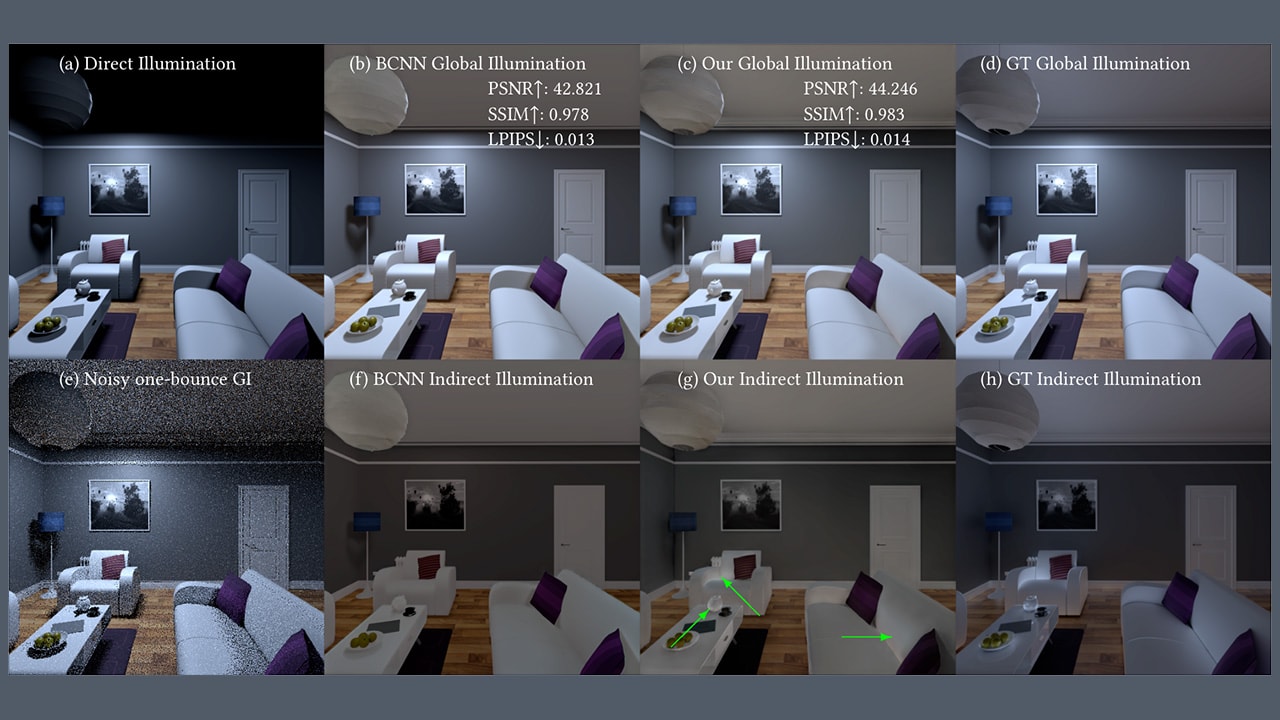
We now turn to training and evaluation. We train on a synthetic dataset of interior scenes rendered with Blender® Cycles and evaluate on unseen scenes. Against a few prior methods, our results are visually closer to the reference and preserve geometric structure from the inputs, while the diffusion baselines show hallucinations and overly bright output (Figure 3). Quantitatively, we lead on PSNR, SSIM, and LPIPS by a large margin and achieve better temporal stability (FovVideoVDP) across all scenes.
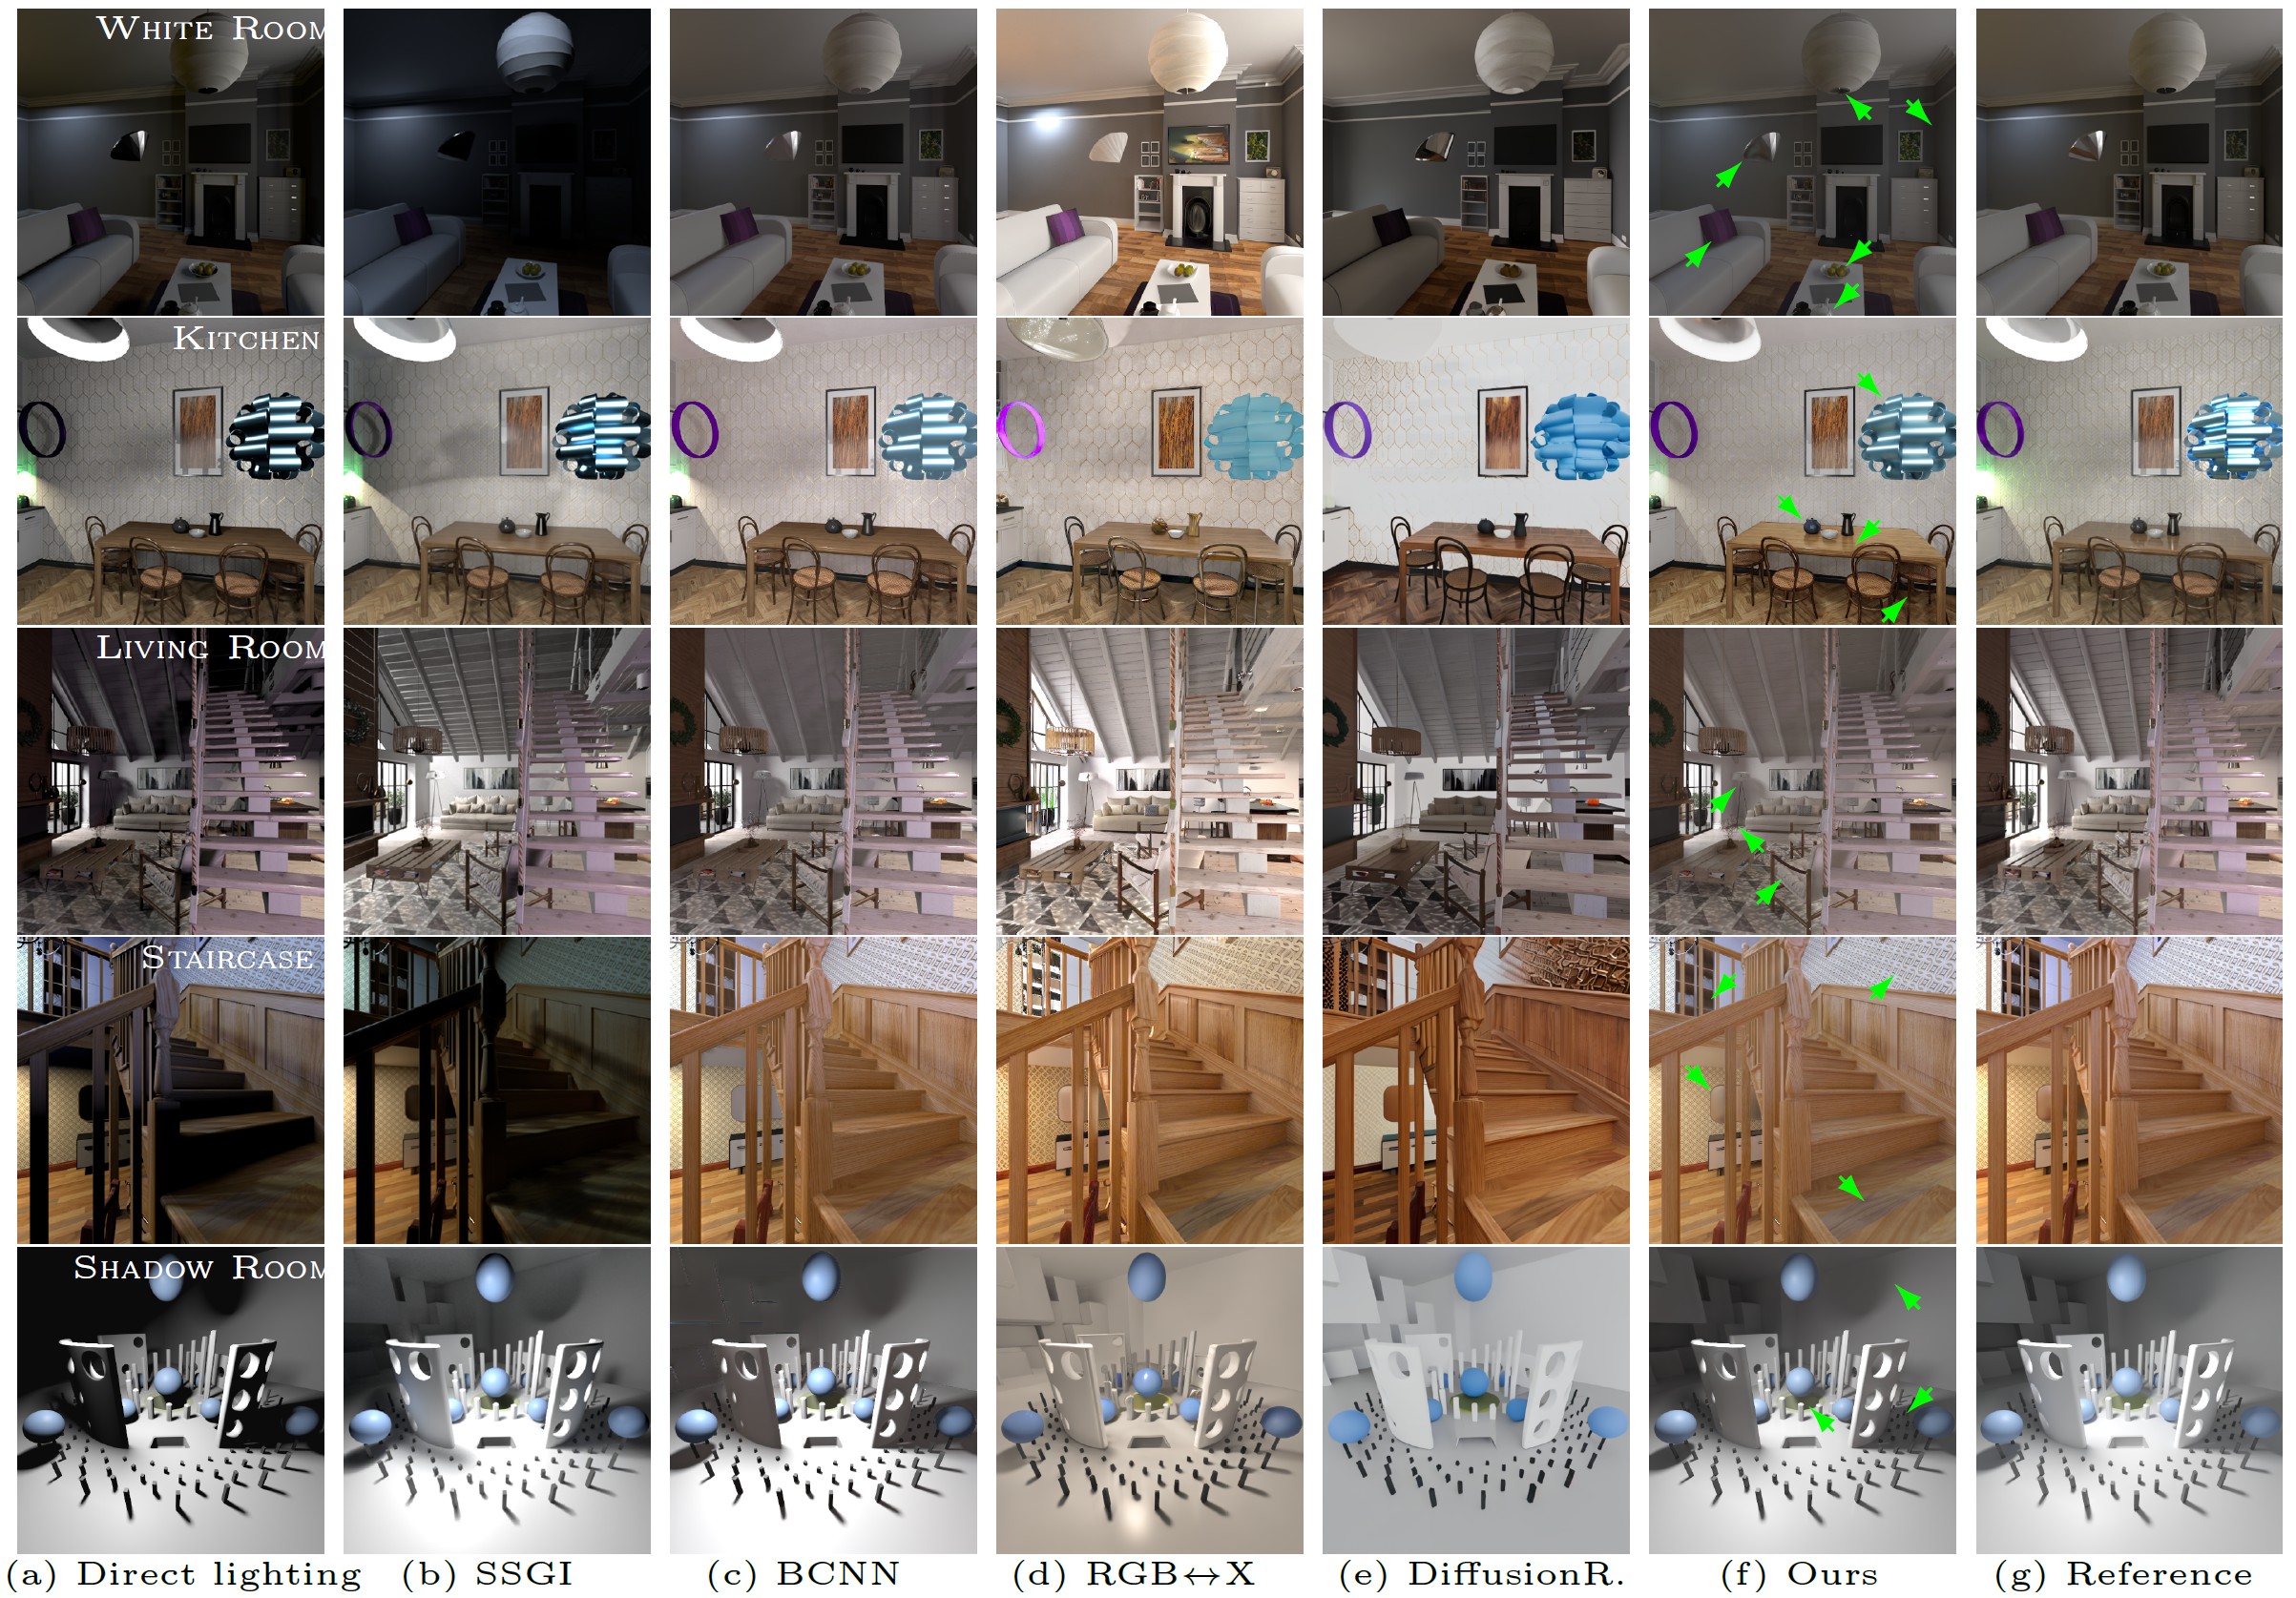 Figure 3. Quality comparison on the test dataset. Direct lighting (a) is the initial hint and the reference (g) is path-traced GI. We compare against SSGI (b), BCNN 1 (c), RGB↔X 2 (d), and DiffusionRenderer 3 (e); arrows on our results (f) mark regions closer to the reference.
Although trained only on synthetic data, the model also adapts to real-world images, where the same conditioning images are not available. A compact variant (Ours-C), conditioned only on signals recoverable by inverse rendering of real-world images, aligns well with the features and illumination of unseen real photos and stays robust even with imperfect intrinsics (Figure 4).
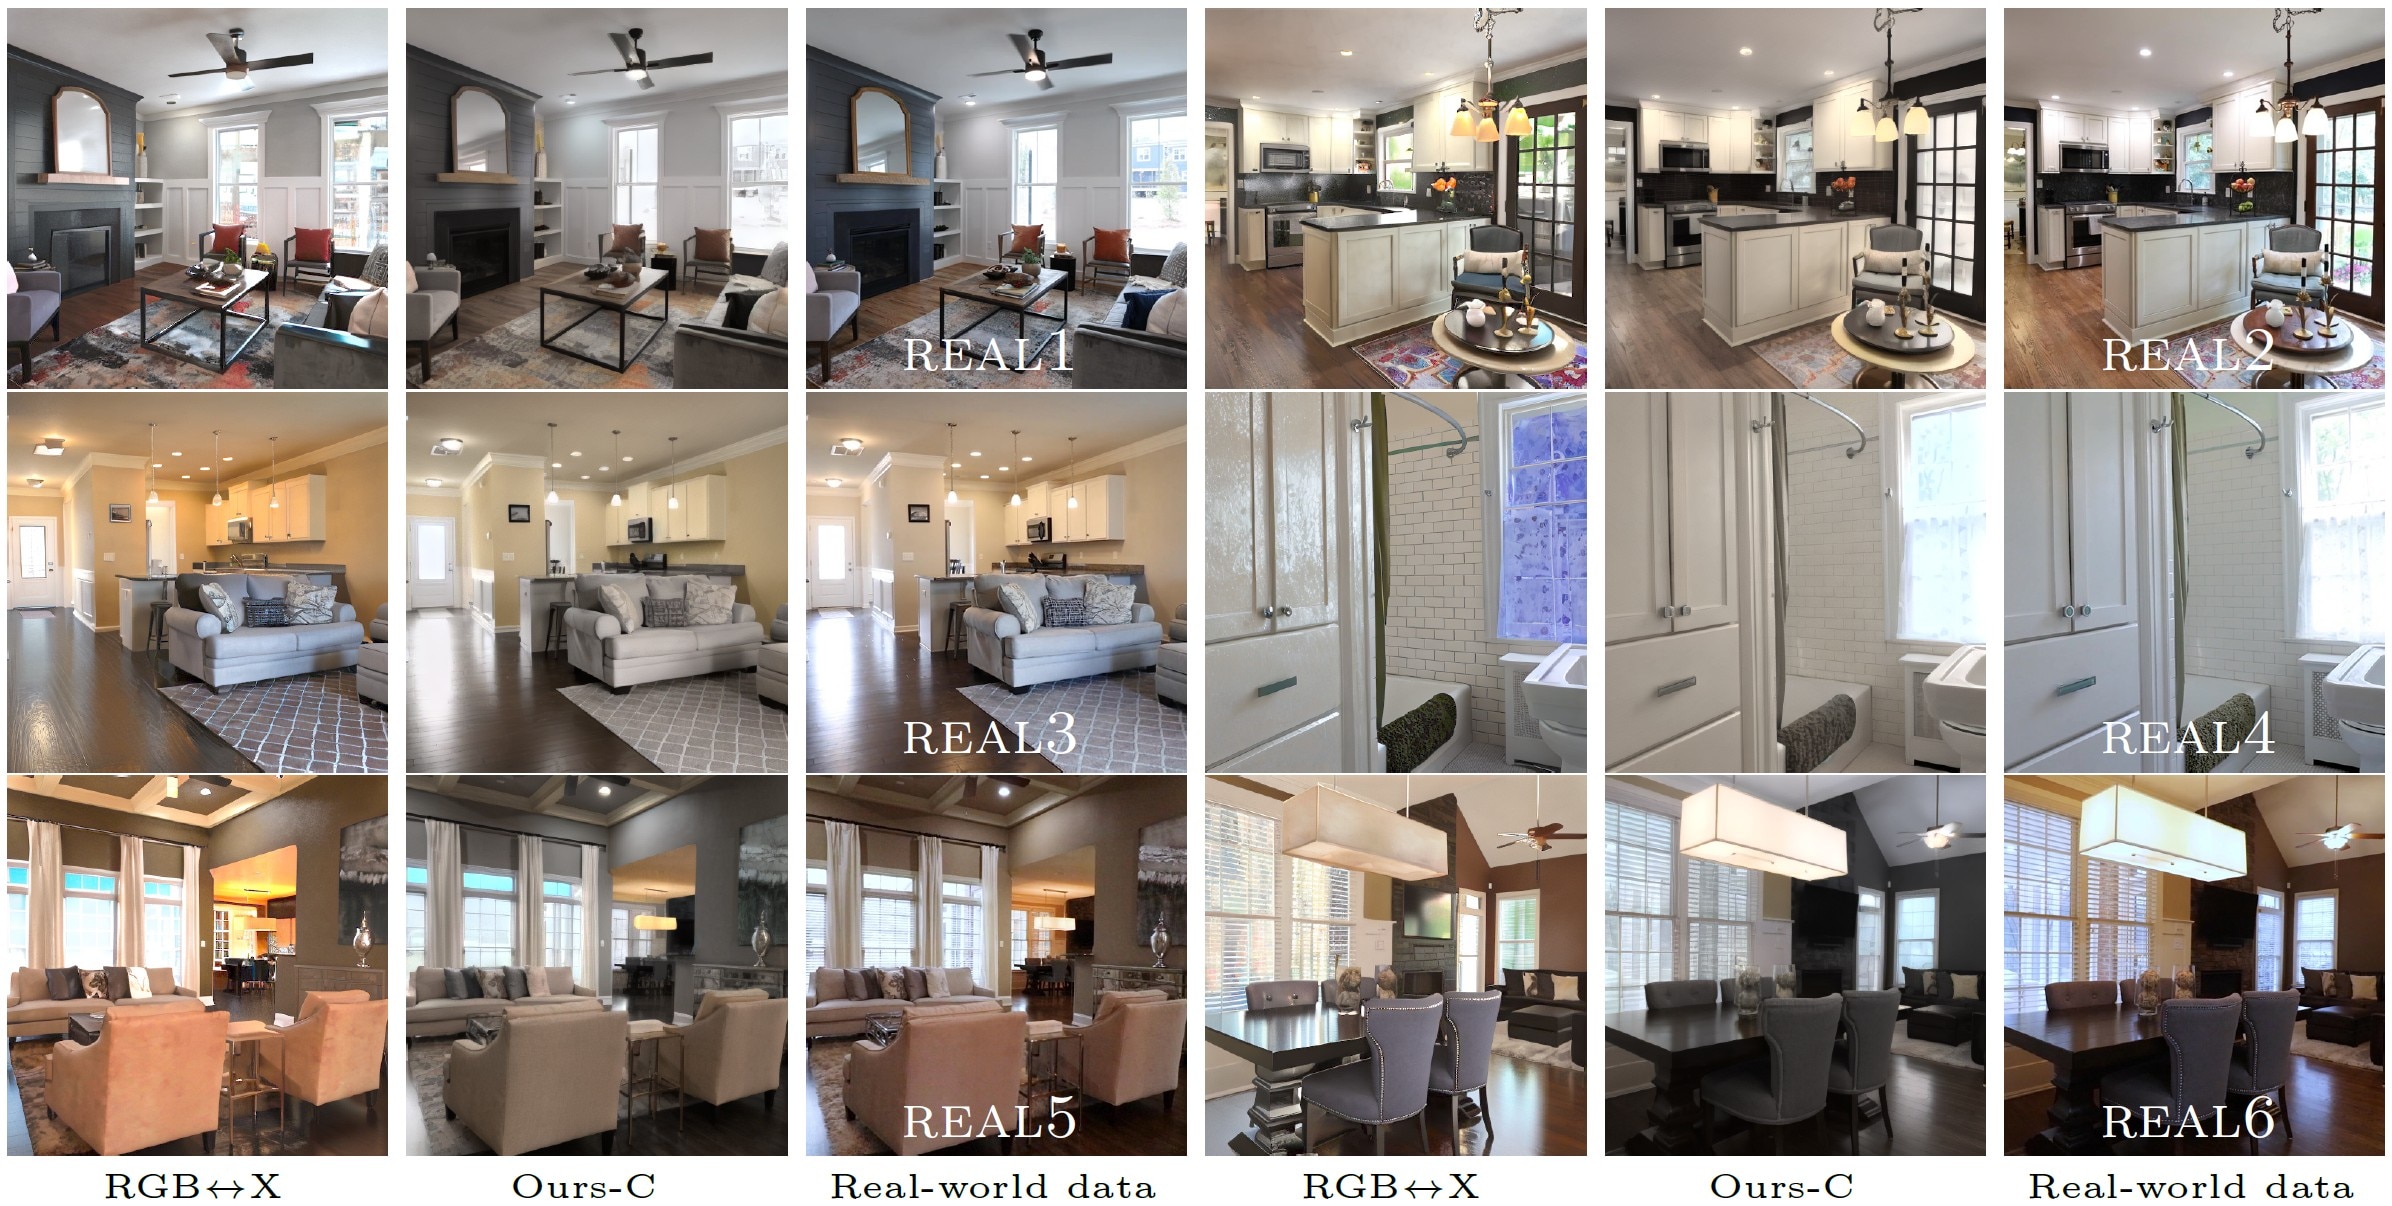 Figure 4. Real-world results compared with RGB↔X. Ours-C uses conditioning inputs obtainable via inverse rendering. Original images courtesy of Pexels.
Figure 5. Our results compared to prior methods and reference ground truth.
Links to third party sites are provided for convenience and unless explicitly stated, AMD is not responsible for the contents of such linked sites and no endorsement is implied. GD-97.
Blender is a registered trademark (®) of the Blender Foundation in EU and USA.
Xin et al. Lightweight Bilateral Convolutional Neural Networks for Interactive Single-Bounce Diffuse Indirect Illumination. TVCG (2020). ↩
Zeng et al. RGB↔X: Image Decomposition and Synthesis using Material- and Lighting-aware Diffusion Models. ACM SIGGRAPH. SIGGRAPH (2024). ↩
Liang et al. DiffusionRenderer: Neural Inverse and Forward Rendering with Video Diffusion Models. CVPR (2025). ↩